Opening Historical Archives
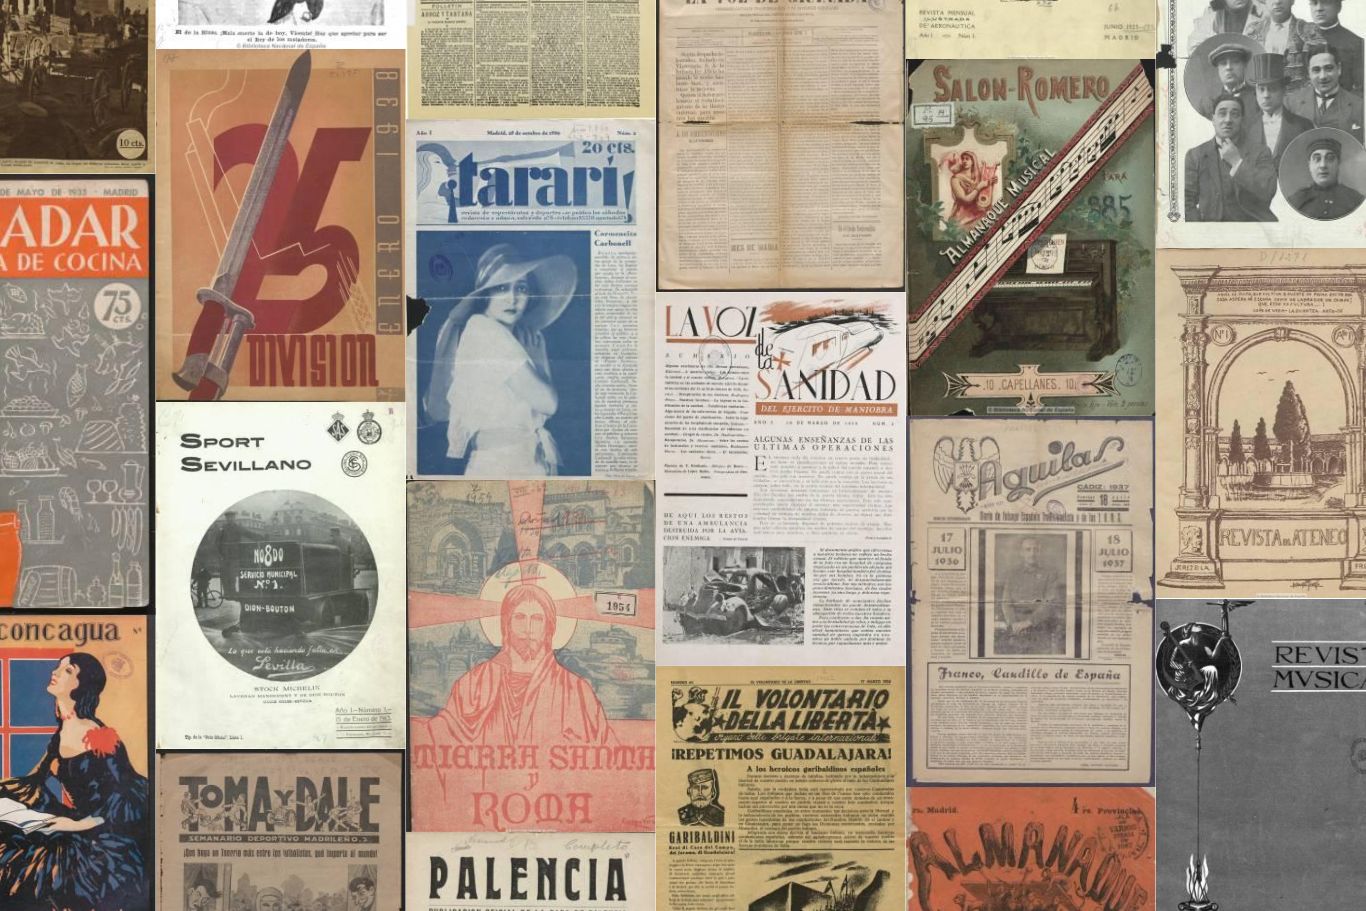
Many libraries and museums have digitized their historical collections, but these documents can be searched most of the time only by catalog details, not by the actual page content. We are working to change that, so researchers and the general public can explore this vast data.
We use frontier OCR models to recognize both the text and structure of each page. We deliver the results in ALTO XML, a format already used by many library and archive systems. We have processed more than 800,000 pages and continue this work with collections in Spain and other countries.
How we work
Leading models, one toolkit
Use leading OCR and vision-language models, including OlmOCR-2, PaddleOCR and GLM-OCR, from a single toolkit. They capture the text, layout and structure of each page.
Formats archives already use
Every page is delivered as ALTO XML v3, a format already used by library and museum search systems. The output works directly with search and highlighting, without custom integration.
Built for large collections
Whether you are processing thousands or millions of pages, our workflows scale with the collection and provide clear reports on progress and quality.
See it in action
Hover over the page to explore the regions the model detected, and toggle the ALTO XML view to see the standard format libraries and archives consume.
Work with us
Are you a library, archive, or museum looking to unlock your collections? Get in touch.